Why non-linear response to random values is always positive?

Viewed 64

I'm creating a non-linear response to a series of random values from {-1, +1} using a simple Volterra kernel: Volterra kernel
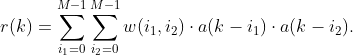
With a zero mean for a(k) values I would expect r(k) to have a zero mean as well for arbitrary w values. However, I get r(k) with an always positive mean value, while a mean for a(k) behaves as expected: is close to zero and changes sign from run to run.

Why don't I get a similar behavior for r(k)? Is it because a(k) are pseudo-random and two different values from a are not actually independent?

Here is a code that I use:

import numpy as np
import matplotlib.pyplot as plt
import itertools

# array of random values {-1, 1}
A = np.random.randint(2, size=10000)
A = [x*2 - 1  for x in A]

# array of random weights
M = 3
w = np.random.rand(int(M*(M+1)/2))

# non-linear response to random values
R = []
for i in range(M, len(A)):
    vals = np.asarray([np.prod(x) for x in itertools.combinations_with_replacement(A[i-M:i], 2)])
    R.append(np.dot(vals, w))

print(np.mean(A), np.var(A))
print(np.mean(R), np.var(R))

Edit:

Check on whether the quadratic form, which is employed by the kernel, is definite-positive fails (i.e. there are negative principal minors). The code to do the check:

import scipy.linalg as lin
wm = np.zeros((M,M))
w_index = 0
# check Sylvester's criterion
# reconstruct weights for quadratic form
for r in range(0,M):
    for c in range(r,M):
        wm[r,c] += w[w_index]/2
        wm[c,r] += w[w_index]/2
        w_index += 1

# check principal minors
for r in range(0,M):
    if lin.det(wm[:r+1,:r+1])<0: print('found negative principal minor of order', r)
2 Answers

I'm not certain if this is the case for Volterra kernels, but many kernels are positive definite, and some kernels, such as covariance functions, do not admit values less than zero (e.g. Squared Exponential/RBF, Rational Quadratic, Matern kernels).

If these are not the cases for the Volterra kernel, you can also try changing the random seed to seed the RNG differently to check if this is still the case. Here is a looped version of your code that iterates over different random seeds:

import numpy as np
import matplotlib.pyplot as plt
import itertools

# Loop over random seeds
for i in range(10):
    
    # Seed the RNG
    np.random.seed(i)

    # array of random values {-1, 1}
    A = np.random.randint(2, size=10000)
    A = [x*2 - 1  for x in A]

    # array of random weights
    M = 3
    w = np.random.rand(int(M*(M+1)/2))

    # non-linear response to random values
    R = []
    for i in range(M, len(A)):
        vals = np.asarray([np.prod(x) for x in itertools.combinations_with_replacement(A[i-M:i], 2)])
        R.append(np.dot(vals, w))
    
    # Covert R to a numpy array to check for slicing
    R = np.array(R)

    print("A: ", np.mean(A), np.var(A))
    print("R <= 0: ", R[R <= 0])
    print("R: ", np.mean(R), np.var(R))

Running this, I get the following values:

A:  0.017 0.9997109999999997
R <= 0:  []
R:  1.487637375177384 0.14880206863520892
A:  -0.0012 0.9999985600000002
R <= 0:  []
R:  2.28108226352669 0.5926651729251319
A:  0.0104 0.9998918400000001
R <= 0:  []
R:  1.6138015284426408 0.9526360372883802
A:  -0.0064 0.9999590399999999
R <= 0:  []
R:  0.988332642595828 0.9650456000380685
A:  0.0026 0.9999932399999998
R <= 0:  [-0.75835076 -0.75835076 -0.75835076 ... -0.75835076 -0.75835076
 -0.75835076]
R:  0.7352258581171865 1.2668744674748733
A:  -0.0048 0.9999769599999996
R <= 0:  [-0.02201476 -0.29894937 -0.29894937 ... -0.02201476 -0.29894937
 -0.02201476]
R:  0.7396699663779303 1.3844391355510492
A:  -0.0012 0.9999985600000002
R <= 0:  []
R:  2.4343947709617475 1.6377776468054106
A:  -0.0052 0.99997296
R <= 0:  []
R:  0.8778918601676095 0.07656607914368625
A:  0.0086 0.99992604
R <= 0:  []
R:  2.3490174001719937 0.059871902764070624
A:  0.0046 0.9999788399999996
R <= 0:  []
R:  1.7699147798471178 1.8049209966313247

So as you can see, R still has some negative values. My guess is that this occurs because your kernel is positive definite.

This question ended up being about math, and not programming. Nevertheless, this is my own answer.

Simply put, when indices of a(k-i) are equal, the variables in the resulting product are not independent (because they are equal). Such a product does not have a zero mean, hence the mean value of the whole equation is shifted into the positive range.

Formally, implemented function is a quadratic form, for which a mean value can be calculated by

E[A^TWA]=tr[W\Sigma]+\mu^TW\mu,

where \mu and \Sigma are a vector of expected values and a covariance matrix for a vector A respectively.

Having a zero vector \mu leaves only the first part of this equation. The resulting estimate can be done with the following code. And it actually gives values that are close to the statistical results in the question.

# Estimate R mean
# sum weights in a main diagonal for quadratic form (matrix trace)
w_sum = 0
w_index = 0
for r in range(0,M):
    for c in range(r,M):
        if r==c: w_sum += w[w_index]
        w_index += 1
Rmean_est = np.var(A) * w_sum
print(Rmean_est)

This estimate uses an assumption, that a elements with different indices are independent. Any implicit dependency due to the nature of pseudo-random generator, if present, probably gives only a slight change to the resulting estimate.

Related